

New Linux tech compresses memory in RAM, as RAM, for 452x speedup
A new compression model, called CRAM, offers a different path to compression that avoids swap entirely by keeping the compressed data in memory, and it offers up to 452x the performance of ZRAM. I was a kid in the 1990s when the idea seemed so simple to me: I can use PKZIP to compress my files, so why can't we do that with RAM? Indeed, I am not a singular genius, and many other people had the same idea, so memory compression has been a feature of most operating systems for a long time. In Linux, the most popular options are zswap and ZRAM, but both of these options are fundamentally swap-layer features. CRAM is a new take that claims to boost performance tremendously.
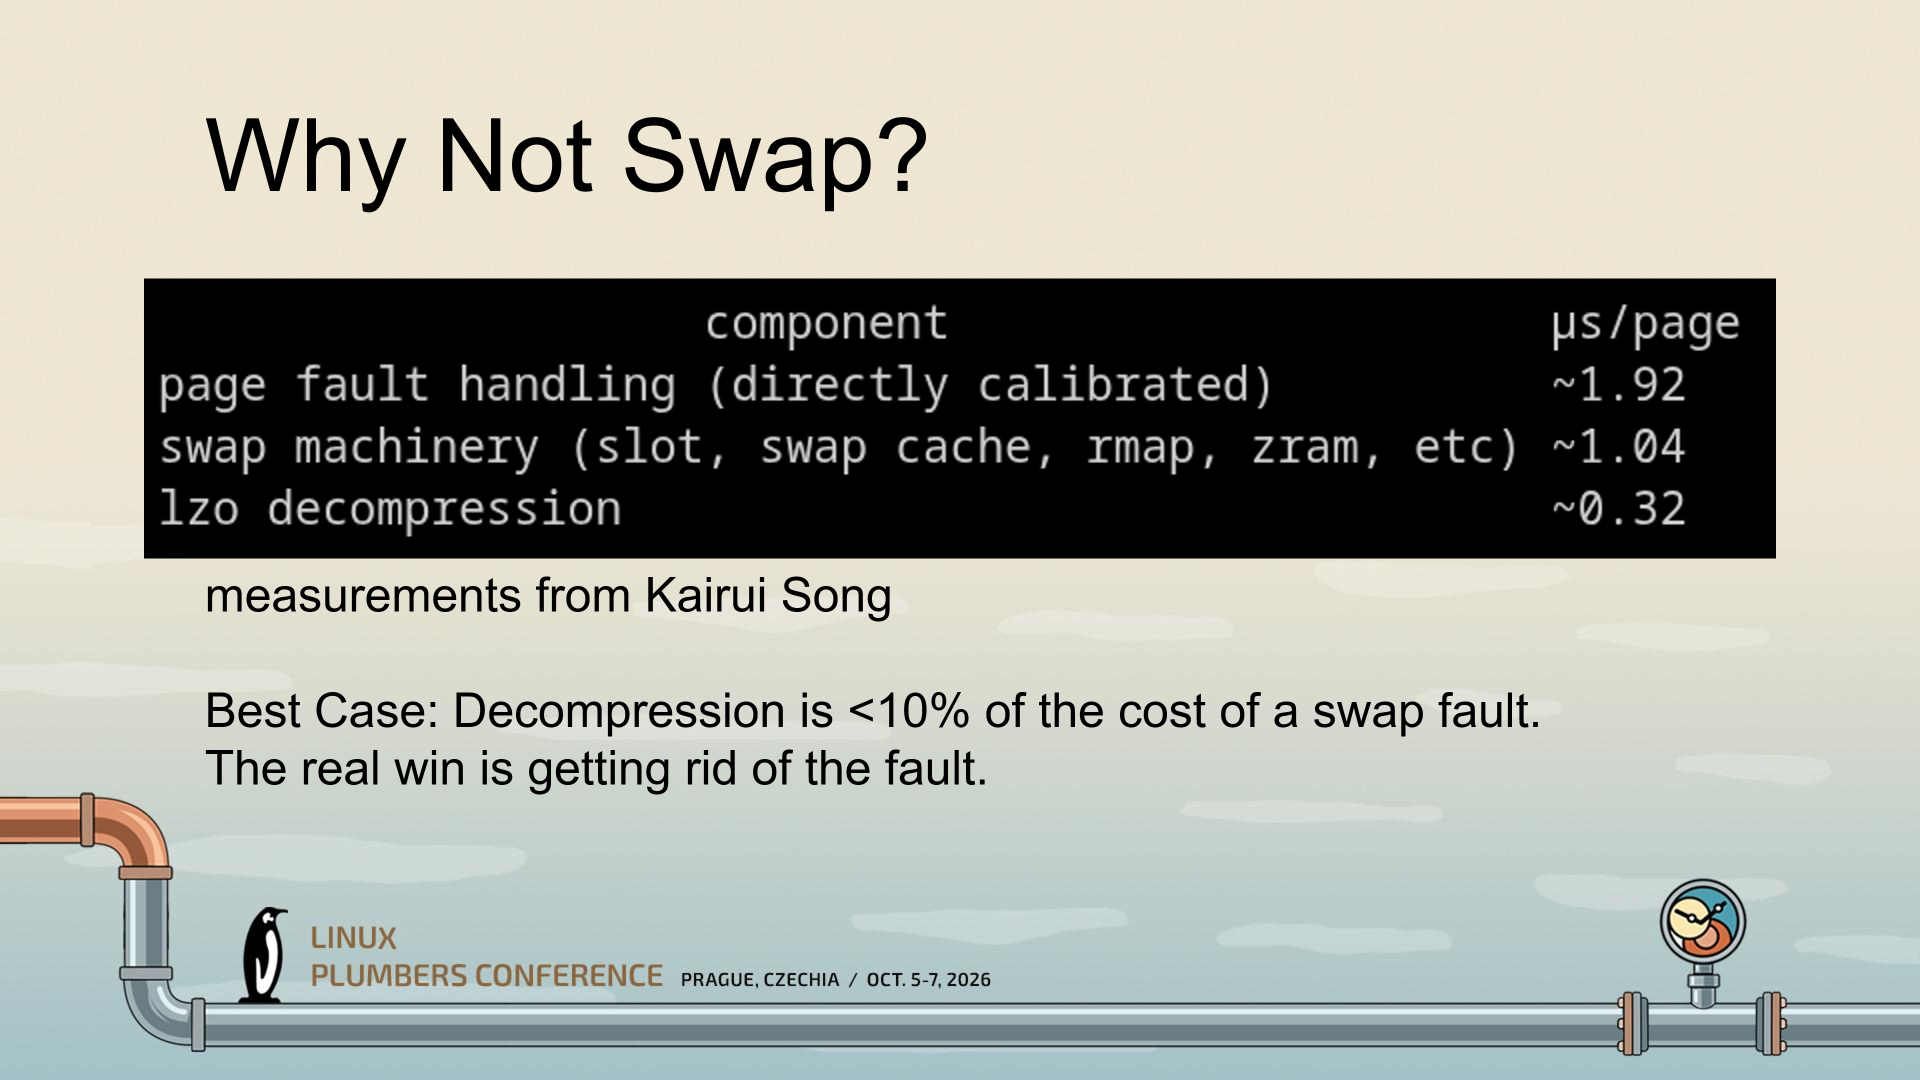
CRAM was conceptualized by Gregory Price and his team at Meta. The central realization that seems to have spurred the development of CRAM is that the largest portion of the performance hit from compressed memory isn't the compression; that's tiny. No, the largest hit apparently stems mostly from the fault itself and the swap behavior. So the thinking seems to have been "what if we just do zram, but completely in memory instead of as swap?"
That's a gross simplification of an enormously complex project, but what CRAM seems to be doing is making use of mechanisms Linux already has to enable radically higher-performance compressed memory, particularly on reads. It uses a private NUMA node (essentially, a ghost CPU) instead of pretending to be a block device, and this lets Linux continue using all of its memory semantics, including migration and ballooning, to manage CRAM.
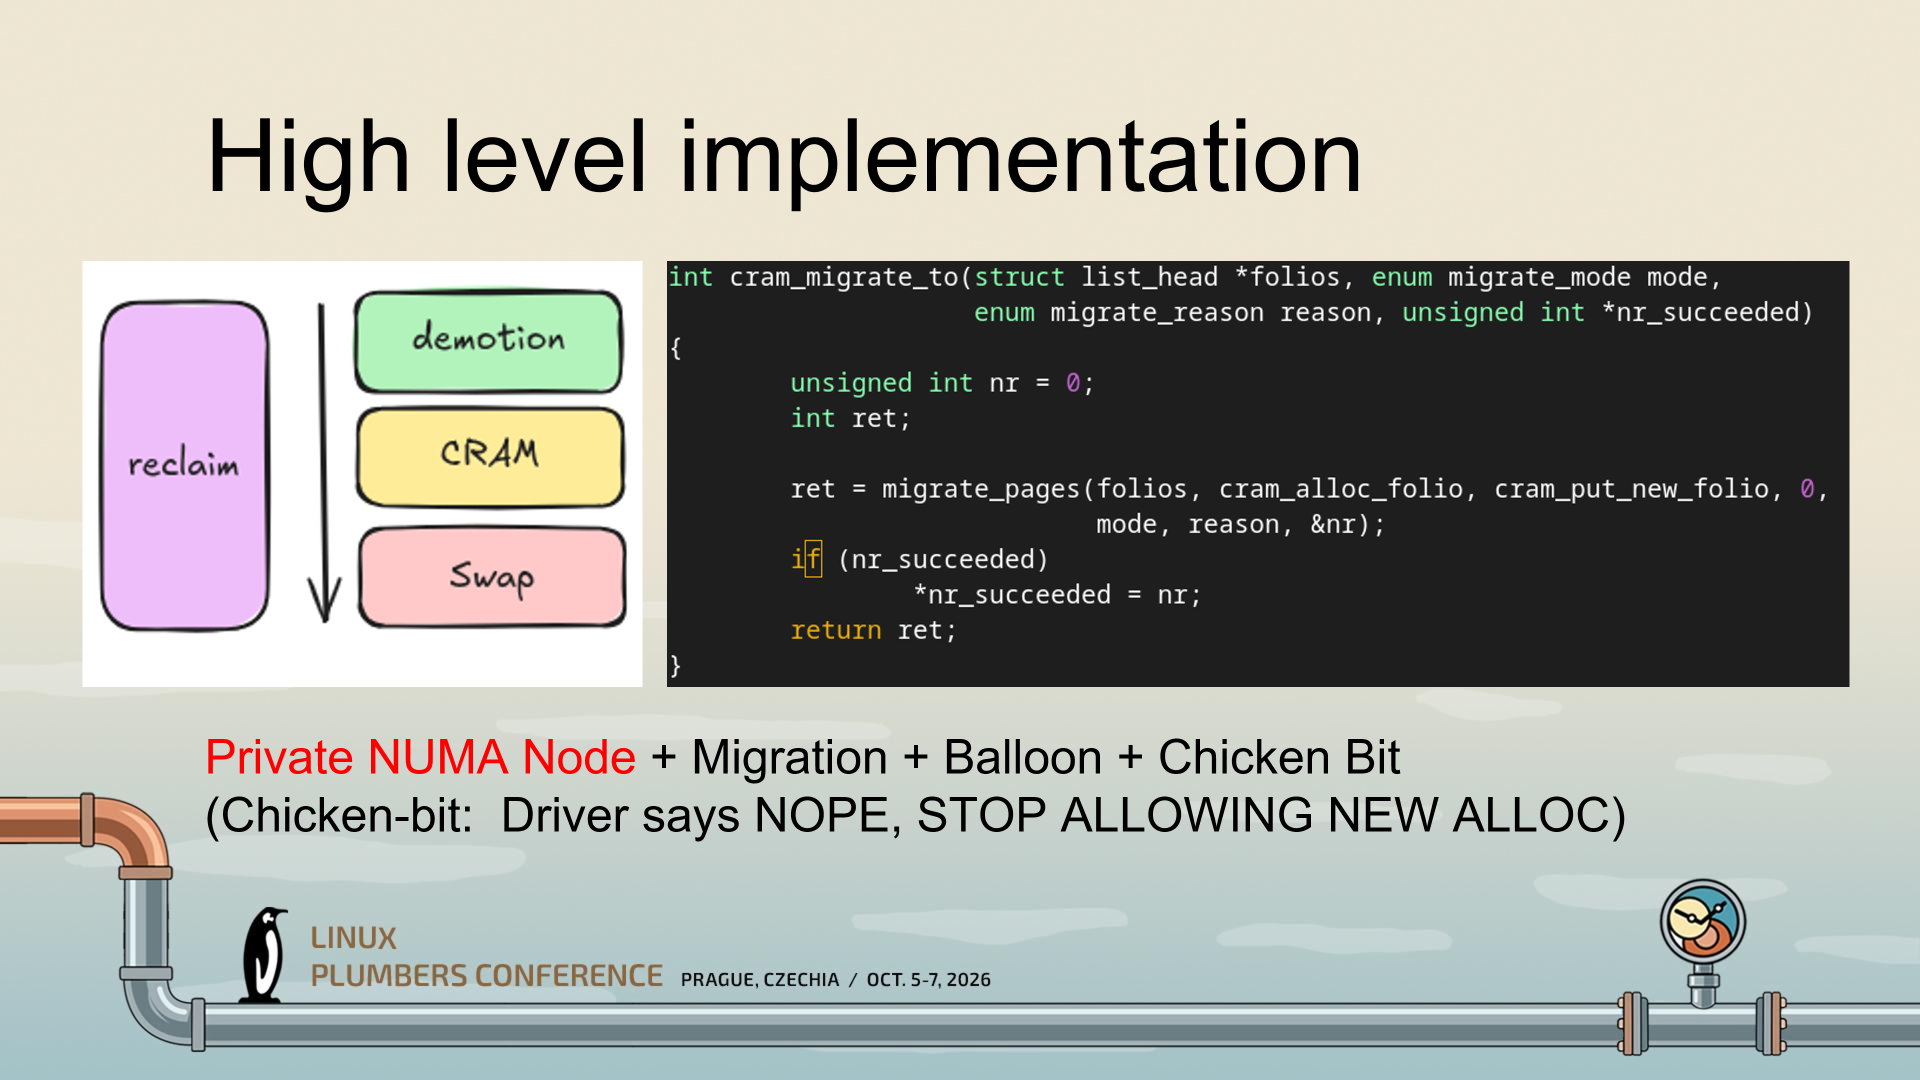
A critical part is the "Chicken Bit," which tells Linux that it has to stop trying to use CRAM while it is busy managing allocations. See, compressed memory seems straightforward until you start actually thinking about it. Compressibility of data varies tremendously based on what you're compressing, all the way from big piles of zeroes (perfectly compressible) up to already-compressed data (non-compressible). Given that, how do you know how much "logical" RAM you have when some of it is compressed? And how do you know when you're going to run out?
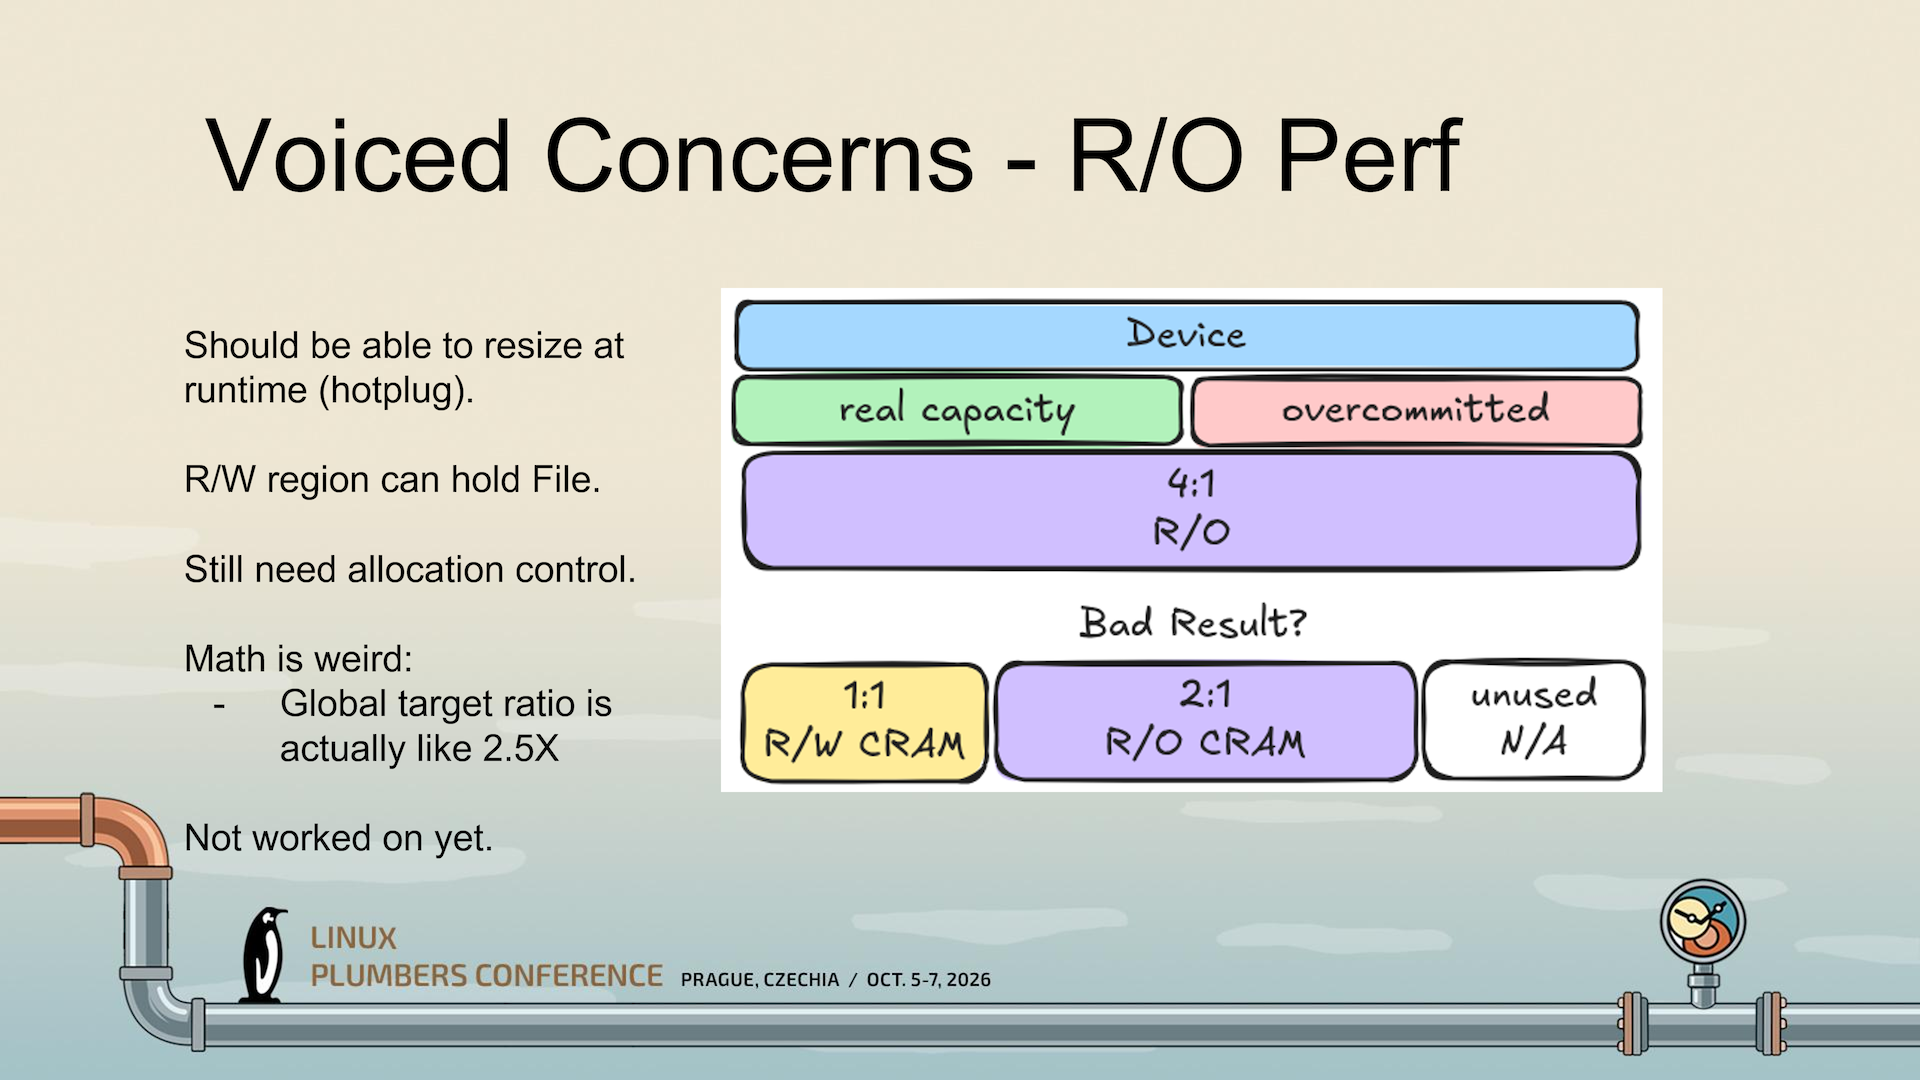
CRAM hasn't actually solved that problem yet, it seems; the slides I'm working from seem to establish this as an unsolved problem and an area of ongoing research. But the Chicken Bit is one way it can at least stop cascading failures (colorfully called a "poison storm" in the presentation) from happening when writes outpace CRAM's ability to allocate them.
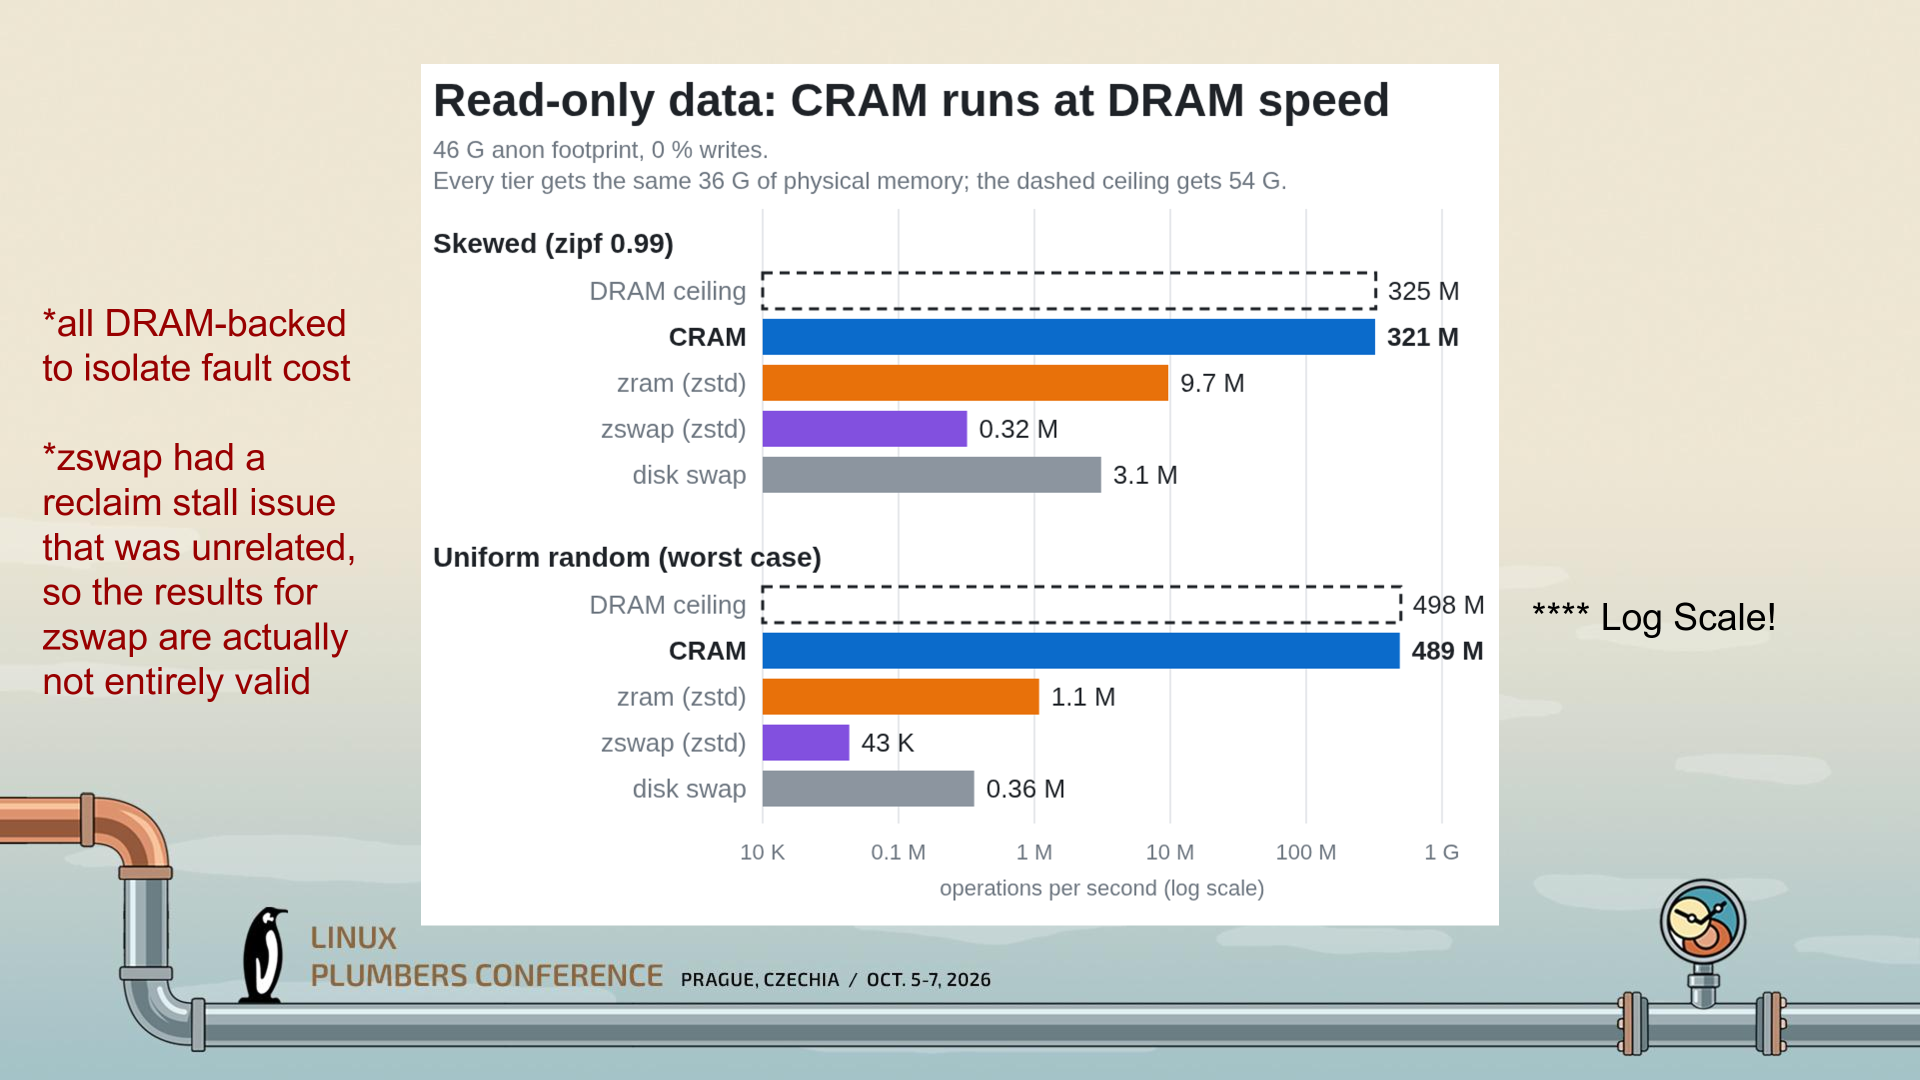
Because CRAM is stored in RAM and treated as RAM, with full cacheline/byte access, it can be accessed in a read-only fashion with little delay; just the cost of hardware-offloaded compression. As a result, CRAM "runs at DRAM speed," as the creator says in the slide above. While the graph already looks impressive, it's a logarithmic scale; CRAM, in the worst case, is doing 489 million operations per second versus ZRAM's 1.1 million. It's barely comparable.
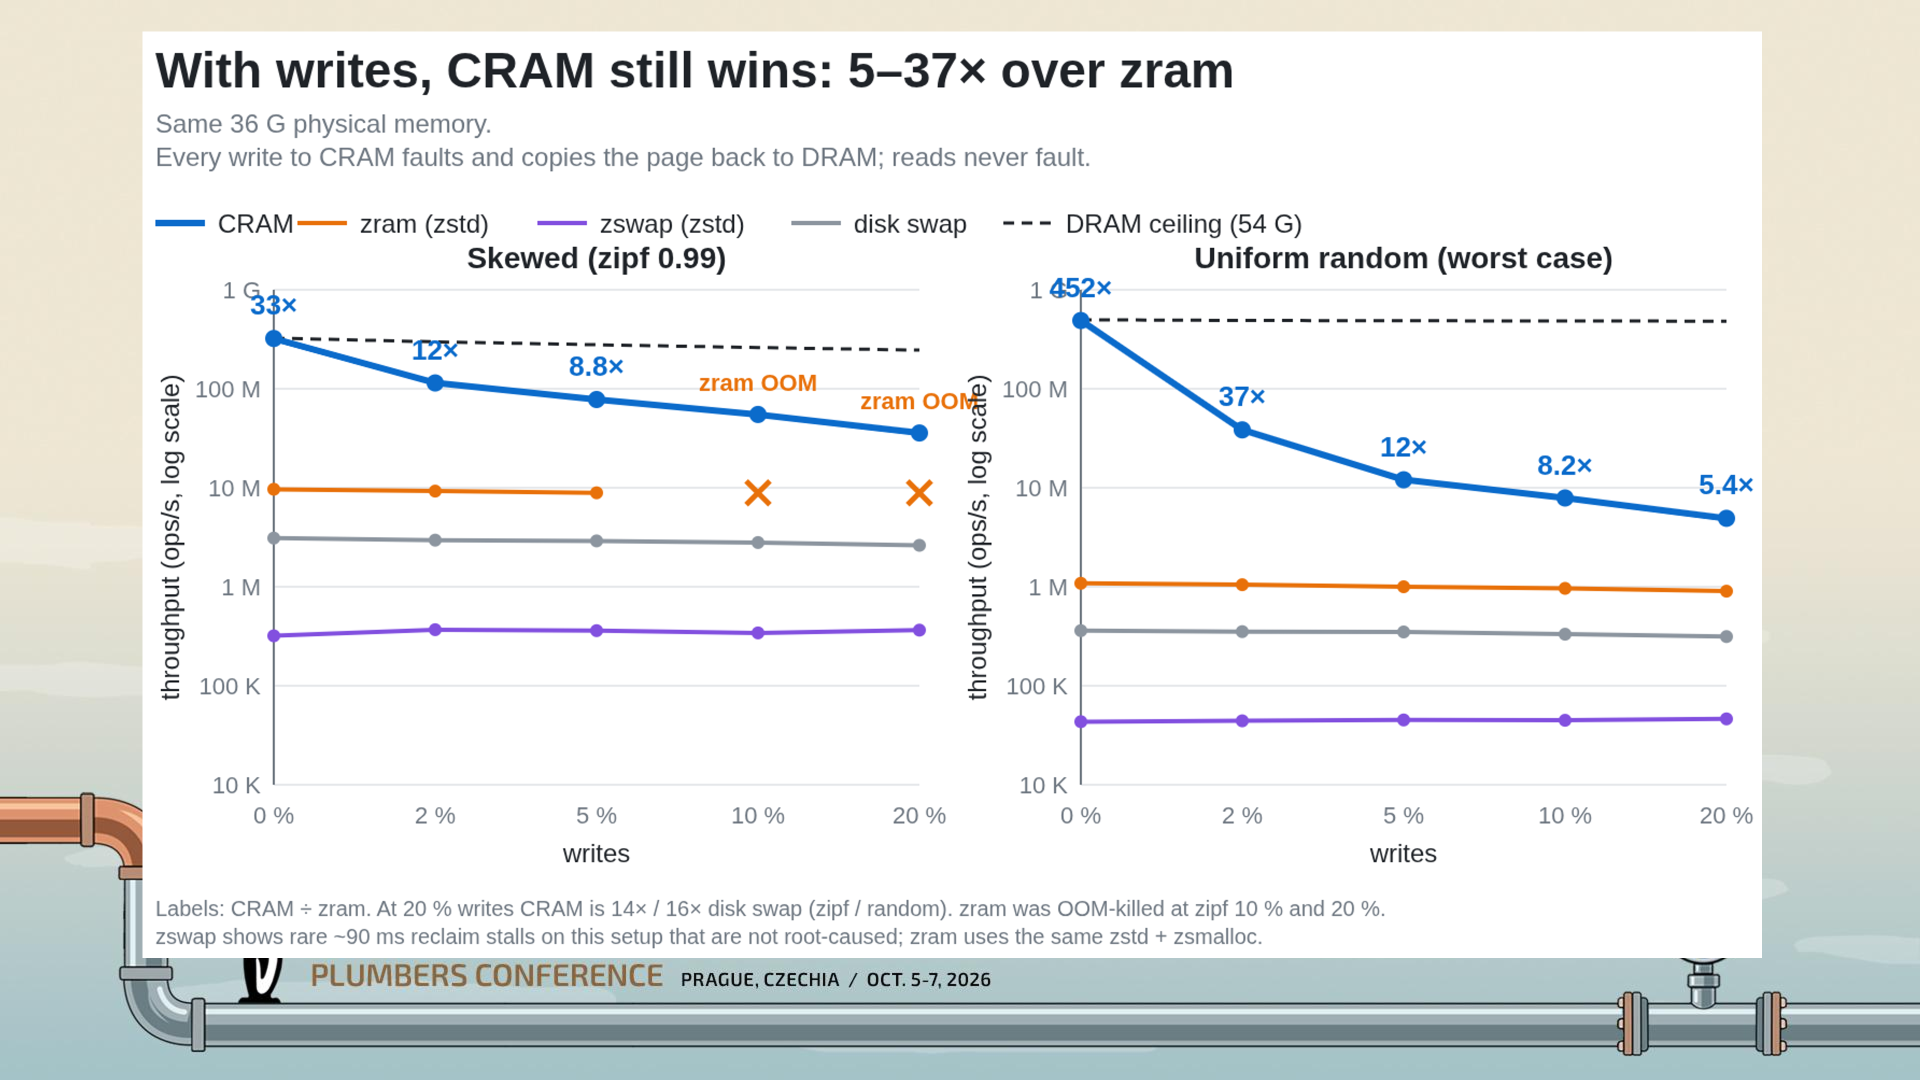
Even when you enable writes, CRAM is still much faster than ZRAM; 5.4x in the worst tested case of 20% writes. That's a huge drop from the 452x read-only case, but keep your context; a 5.4x speedup is still titanic. The massive performance cliff when writes are involved comes down to the need to page fault and migrate folios back to the original NUMA domain, as you can't write directly to compressed data; you'd corrupt everything.
My explanation of CRAM might not be completely correct; I wasn't at the Linux Plumbers' Conference in Prague to hear the presentation directly, so I'm working off of the slides available from the session information site (h/t to Phoronix for the spot) I think I've managed to grasp the gist of what Price is getting at, though.
While the obvious target of the work here (given its origin at Meta Platforms) is big Linux servers, ZRAM and Zswap are used all over the Linux ecosystem, even on machines as constrained as the Steam Deck. Many distributions enable one or the other by default. CRAM seems like it could offer a considerable speed-up for some of these machines, so hopefully it finds its way into the kernel once the remaining implementation questions are answered.
What's Your Reaction?
 Like
0
 Dislike
0
 Love
0
 Funny
0
 Angry
0
 Sad
0
 Wow
0